Usage-based GPU access
Planned hourly GPU access for inference, model serving, rendering and batch processing. Start with the workload, GPU memory and usage window you need.
DISTRIBUTED GPU INFRASTRUCTURE
ETERNApod is developing a distributed GPU cloud: modular pods at sites with suitable power and fibre, connected through one shared software layer. Planned access for inference, rendering and AI workloads—without buying your own GPU infrastructure.
For investors & strategic partnersIn development · First milestone: prototype validation
01 / VISION
Built to grow across locations.
ETERNApod aims to use existing power and fibre at suitable residential, industrial and educational sites through modular GPU pods. The proposed architecture connects pods across locations into one centrally managed service network.
FOR AI TEAMS & ENTERPRISES
Tell us what you want to run.
We will assess a suitable pilot configuration.
Planned hourly GPU access for inference, model serving, rendering and batch processing. Start with the workload, GPU memory and usage window you need.
A planned route for teams with predictable demand: discuss an agreed capacity allocation, schedule and commercial term.
Scope a defined use case before a longer commitment. Review hardware fit, data handling, performance criteria and integration needs together.
Pre-launch enquiries. Pricing, availability and service terms will be confirmed after technical review and prototype validation.
Discuss a pilotFOR SITE OWNERS
The proposed host model turns suitable space, power and fibre into a location for a centrally operated GPU pod.
Propose a locationSpace, power capacity, fibre connectivity and physical access, subject to a site assessment.
The proposed operator model covers hardware operation, central orchestration, and power and internet costs.
The host receives agreed fixed rent under a hosting contract. Terms depend on site suitability and deployment approval.
FOR INVESTORS & STRATEGIC PARTNERS
A phased infrastructure model: deploy repeatable GPU units, connect capacity through shared software, and expand as technical validation and customer demand support the next step.
Planned GPU usage fees, reserved capacity agreements, AI usage credits and storage services.
Pods at qualified host sites. Central management coordinates allocation and operations across locations.
Prototype testing, paid pilots, utilisation and operating costs inform each fleet and facility decision.
Development-stage initiative. Fleet and campus figures are targets. Investment discussions are subject to due diligence and agreed terms.
Discuss the opportunity02 / OUR APPROACH
One location. One pod. A shared network.
Explore the three components of the model.
PROPOSED SERVICE MODEL
Model serving, batch processing, rendering and suitable fine-tuning workloads for AI teams. Planned options include hourly GPU usage, reserved capacity, AI usage credits and storage.
Services are part of the development roadmap.03 / HOW THE NETWORK WORKS
Compute requirements from AI teams and enterprise users.
A planned shared access layer for capacity requests, usage tracking and billing.
Software designed to route workloads to suitable pods and manage capacity and continuity.
Modular GPU units across locations, operating under shared management.
This is the proposed architecture. Network and service performance will be validated through prototype and fleet testing.
04 / THE FIRST POD
Target configuration for Phase 1.
An engineering design to validate through testing.
RTX PRO 6000 Blackwell
Combined GPU memory
Target peak power draw
Steel cabinet form factor
Target values. Final hardware specifications depend on procurement and prototype testing. Raw storage differs from usable capacity.
05 / SCALING ROADMAP
Each stage validates the foundations for the next. The figures below represent phased development targets, not operational capacity.
FIRST VALIDATION MILESTONE
Validate the first pod through a 72-hour load test, power consumption and noise measurements, installation checks and pilot use cases.
Priority: a repeatable, measurable first unit.
06 / WHO IT IS FOR
Flexible capacity for model serving, inference, rendering, batch processing and suitable fine-tuning applications.
A fixed-rent hosting model for sites with suitable power, fibre and physical access. The operator is expected to cover power and internet costs.
Opportunities to participate in hardware, energy, locations and infrastructure as the development programme moves from prototype to scale.
07 / YOUR QUESTIONS
The initiative is in development. The first objective is prototype production and technical validation. Capacity, production timelines and growth figures on this site are targets, not an operational fleet or service guarantees.
No. Power capacity, fibre connectivity, physical access, cooling conditions and required permissions must be assessed for each site. Hosting arrangements follow this suitability review.
The target is a 45-day standard cycle, or 30 days with all components in stock. These timelines depend on component availability and supply agreements; they are not guaranteed delivery times. Critical components that are out of stock can significantly extend the schedule.
The focus is inference, model serving, batch jobs and suitable fine-tuning applications. Due to latency between locations, large model training requiring tightly synchronised operation across thousands of GPUs is outside the initial distributed model’s focus.
ETERNApod is being developed with the support of HANSconstruction and ETERNA+ Partners. HANSconstruction brings construction and delivery experience, while ETERNA+ Partners contributes its architectural and design approach to this infrastructure vision.
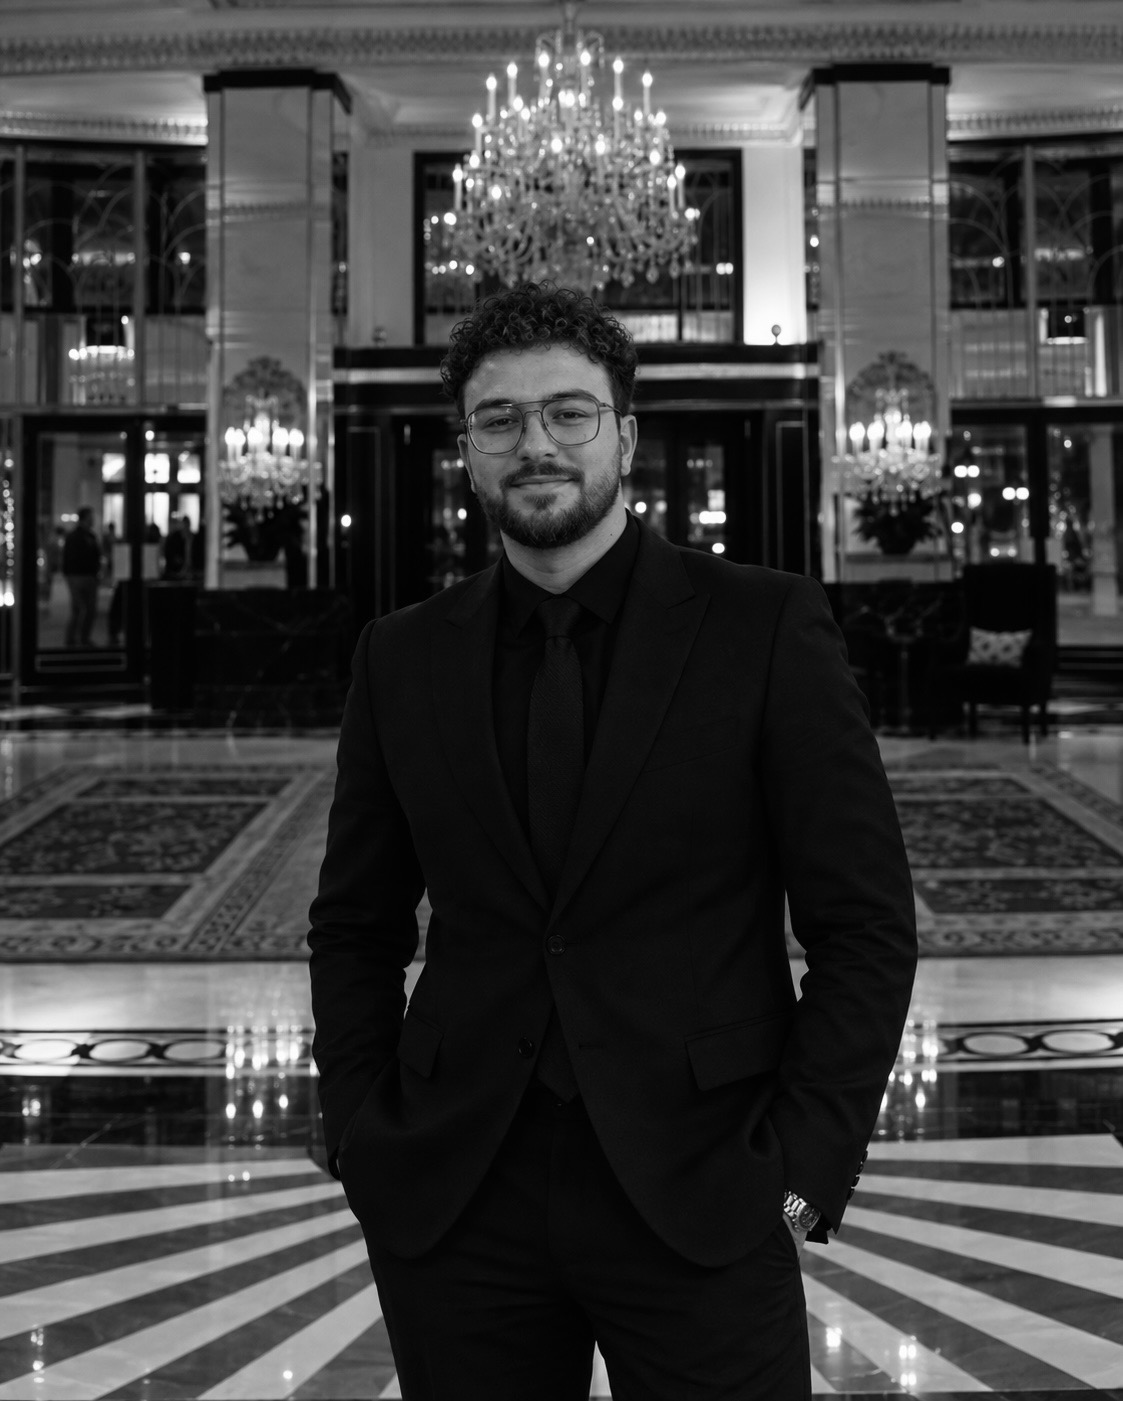
08 / A NOTE FROM OUR CEO
“A bold vision earns trust by proving itself in small steps. With ETERNApod, our ambition is to bring engineering, design and sound management together to develop scalable AI infrastructure. Validate first, then grow. For me, that is where lasting value begins.”
CEO
HANSconstruction · ETERNA+ Partners
Bringing together a background in civil engineering, architecture and construction management, Veli Tunahan Bay has led HANSconstruction and ETERNA+ Partners since 2019.
Education: London Metropolitan University · Architecture, 2022–2025.
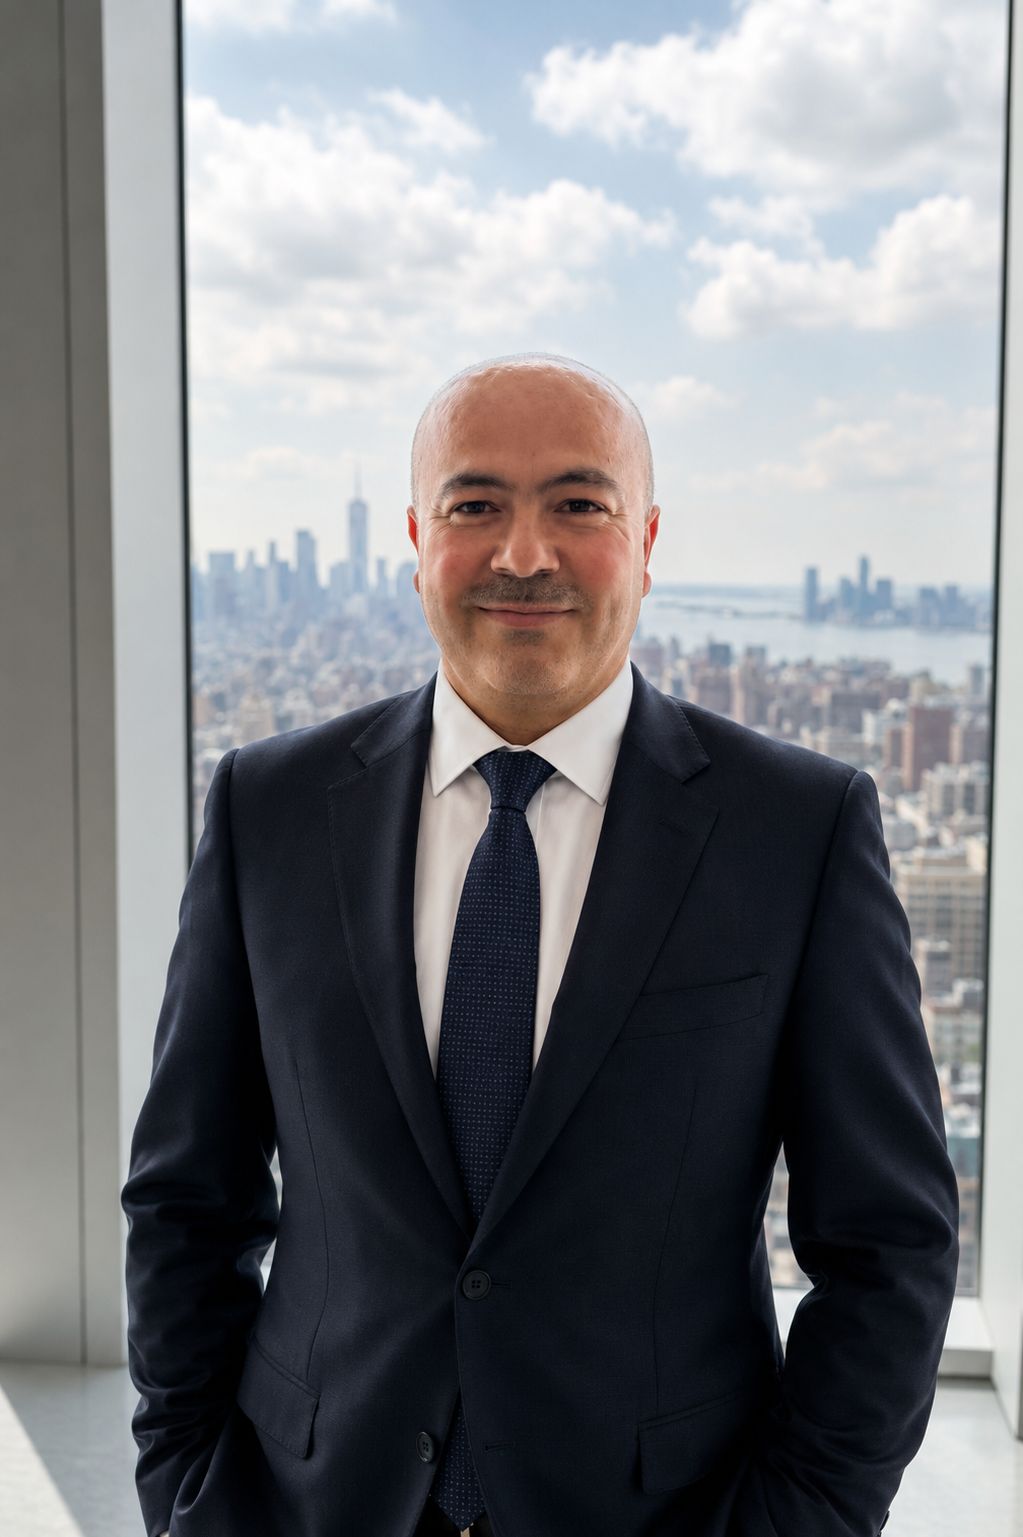
STRATEGIC ADVISOR
Strategic & Capital Markets Advisor
Founder & CEO, FinSPAX LLC (USA)
25+ years of U.S. capital markets experience, specializing in capital raising strategy, investor relations, SPAC transactions and U.S. public market access.
Education: Long Island University, 2000–2004.
09 / CONTACT
Discuss a pilot, a host partnership or an investment opportunity.
Istanbul / Maslak · London / Mayfair, W1J 6BD